Rescribe
by Rescribe Ltd
OCR images, PDFs and Google Books


About
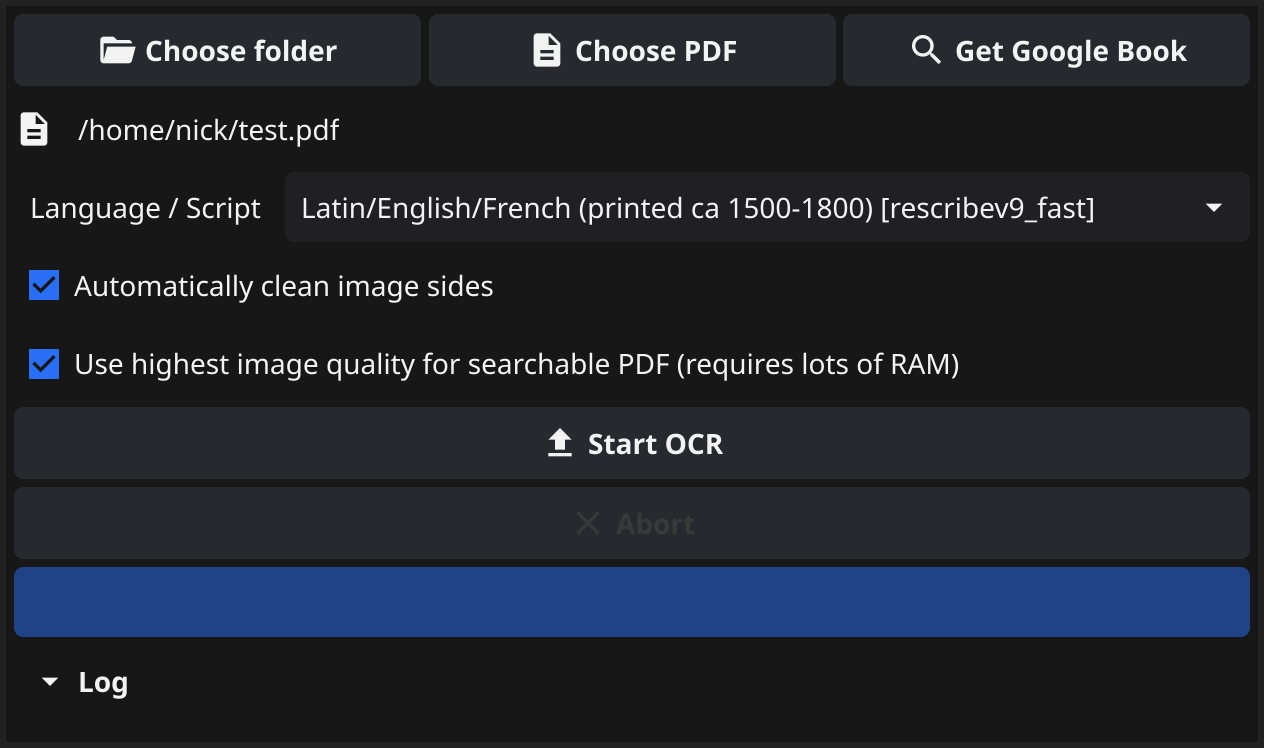
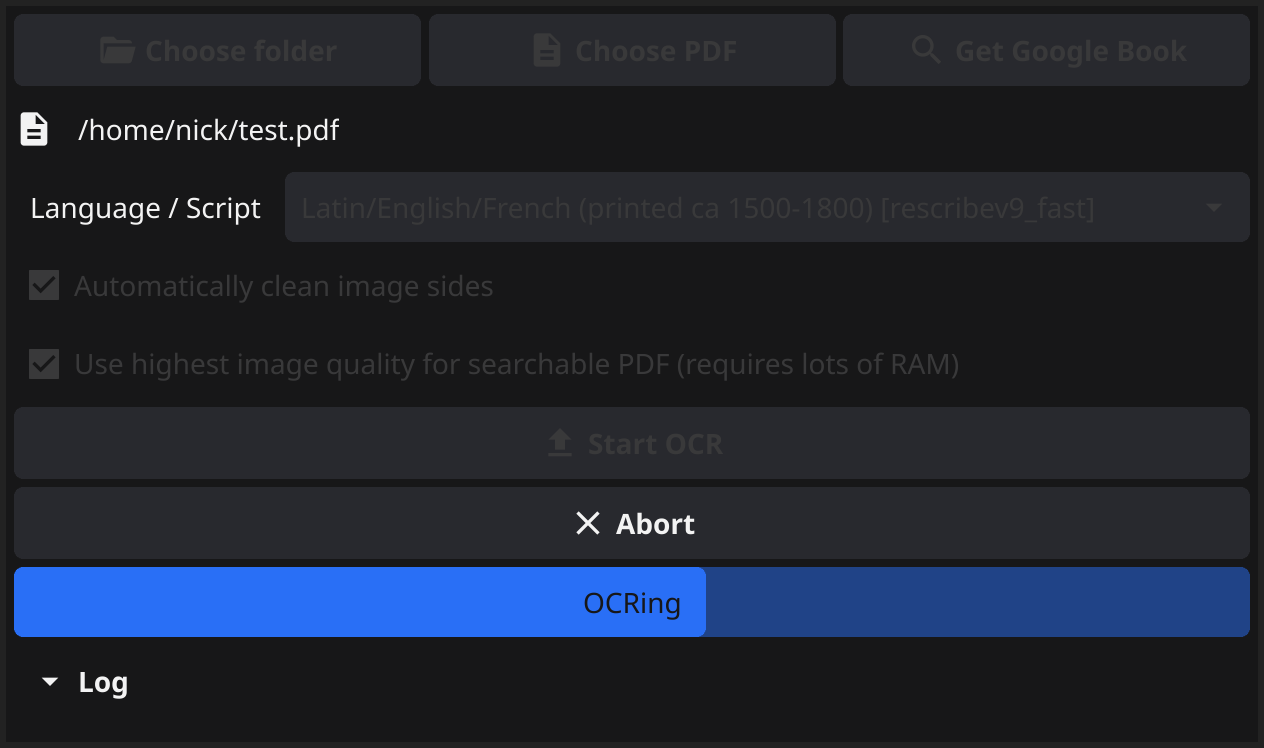
An easy-to-use desktop tool to recognise and extract text from images, PDFs and Google Books. It uses the Tesseract OCR engine, combined with modern and efficient preprocessing and analysis pipelines, to produce high quality output in plain text, hOCR and searchable PDF format. The tool has been built with a focus on OCR of historical printed works, but it includes modern language options and also works well on modern printed works.
Permissions
2 permissions weaken the sandbox. Flatsonar asks before installing.
- X11 display: X11 lets apps read input and windows of other apps
--socket=x11 - full access to your home folder
--filesystem=home - network
--share=network - inter-process communication (needed for X11)
--share=ipc - Wayland display
--socket=wayland - X11 display, only when Wayland is unavailable
--socket=fallback-x11 - GPU acceleration
--device=dri
Who publishes this
The creator demonstrably controls this app id: Flathub verification, the hosting account owns the namespace, or a well-known file on their domain.
- verified on Flathub: the developer proved they control this app id
publisher:flathub
Maintenance
Recent activity on the upstream repository, or built and reviewed by Flathub.
No staleness signals: recent activity, or built and reviewed by Flathub.